K Means Prediction R
Flexclust is a package that is designed around K-centroid cluster analysis. Clustering analysis is performed and the results are interpreted.
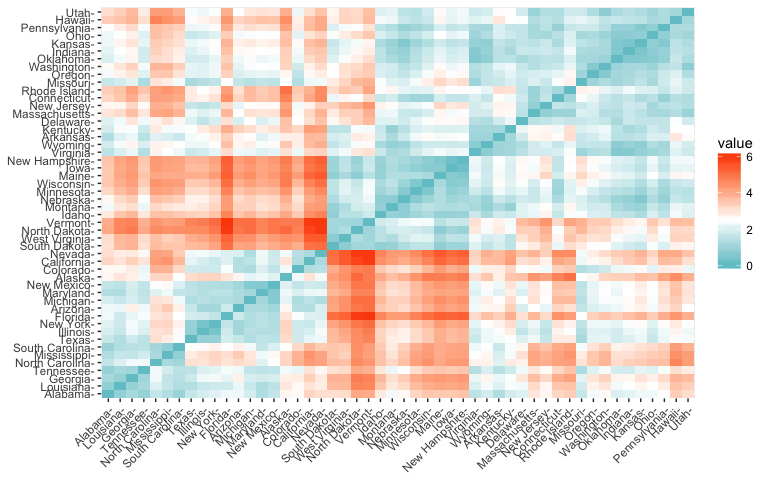
K Means Cluster Analysis Uc Business Analytics R Programming Guide
Let us take an example of k 2 and 5 data points.
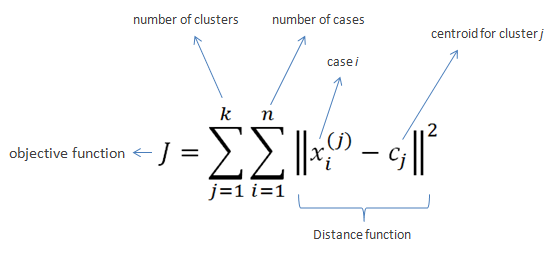
K means prediction r. Perform k-means clustering on a data matrix. It tries to make the intra-cluster data points as similar as possible. Custom K means code in R.
That can be done as predictkmeans. K-Means Clustering in R. RpredictkMeansR Description This function assigns observations in the data matrix newData the most likeliest clusters using the best solution from a kMeans object.
The aim of this project is to form a simple understandable k means code for beginners in R. I have introduced certain good elements of R like data frames but the computations are mostly of a Pythonic. I am sure people who are from other programming languages will find this useful as its flavour is not completely R.
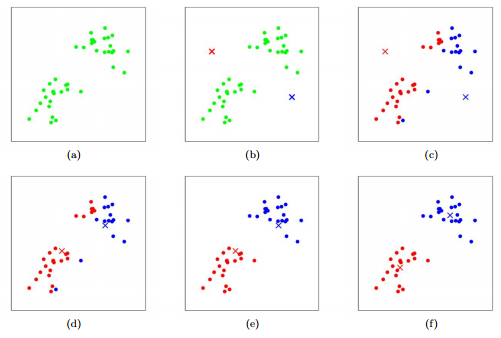
You can see each step graphically with the great package build by Yi Hui also creator of Knit for Rmarkdown. In figure three you detailed how the algorithm works. K-means clustering MacQueen 1967 is one of the most commonly used unsupervised machine learning algorithm for partitioning a given data set into a set of k groups ie.
R base has a function to run the k mean algorithm. Defines functions predictkMeans Documented in predictkMeans predictkMeans. To perform k-means clustering in R we can use the built-in kmeans function which uses the following syntax.
In this video I go over how to perform k-means clustering using r statistical computing. Given how k-means algorithm works what we want is to find which clusters center is closest to x. Kmeans algorithm is an iterative algorithm that tries to partition the dataset into Kpre-defined distinct non-overlapping subgroups clusters where each data point belongs to only one group.
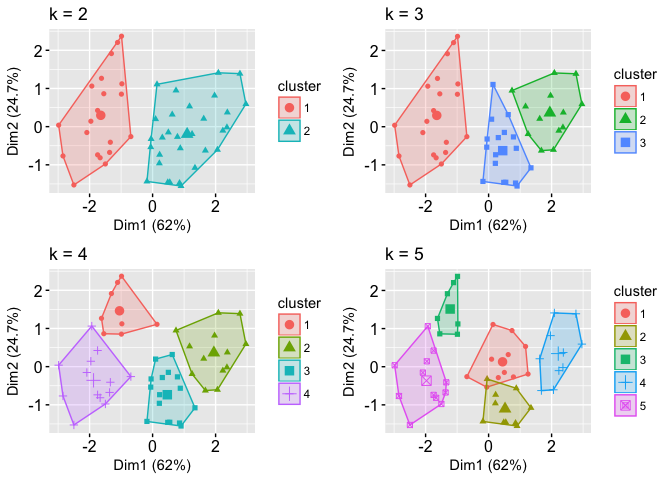
In below example red and green color shows 2 clusters with their respective random data points assigned to them. The function fviz_cluster factoextra package can be used to easily visualize k-means clusters. The number of clusters denoted k.
When you predict only one case iris114 d becomes a vector not a matrix what causes an error on the next step. Predictkmeans. The number of initial configurations.
Using the factoextra R package. Randomly assign each data point to a cluster. K-means clustering is quick and dirty and generally provides some interesting results.
Algorithm and Practical Examples. Number of clusters Train the model. The basic function of k mean is.
K-means clustering implementation in R To implement k-means clustering we simply use the in-built kmeans function in R and specify the number of clusters K. Name of the dataset. Thats where flexclust comes in.
However the default kmeans function in R lacks features such as actually storing the model to use the centroids for prediction purposes on unseen data. K-Means Clustering in R Specify number of clusters K. Its most Read More Storing a K-means.
It takes k-means results and the original data as arguments. Usage kmeansx centers itermax 10 nstart 1 algorithm cHartigan-Wong Lloyd Forgy MacQueen traceFALSE S3 method for kmeans fittedobject method ccenters classes Arguments. In the resulting plot observations are represented by points using principal components if the number of variables is greater than 2.
K clusters where k represents the number of. Dataset used to run the algorithm -k. Explicitly specify variables predictkmeanskmiris114.
Kmeans data centers nstart where.
Cs221
K Means Cluster Analysis Uc Business Analytics R Programming Guide
K Means

Posting Komentar untuk "K Means Prediction R"