K Means Prediction Python
K means is one of the most popular Unsupervised Machine Learning Algorithms Used for Solving Classification Problems. Making Predictions With Our K Means Clustering Model.
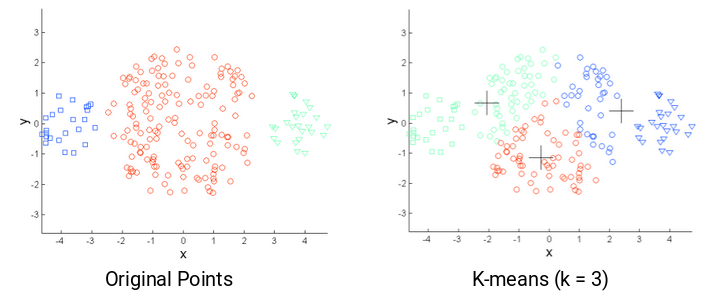
K Means Clustering K Means Clustering Algorithm In Python
For center in centroids.
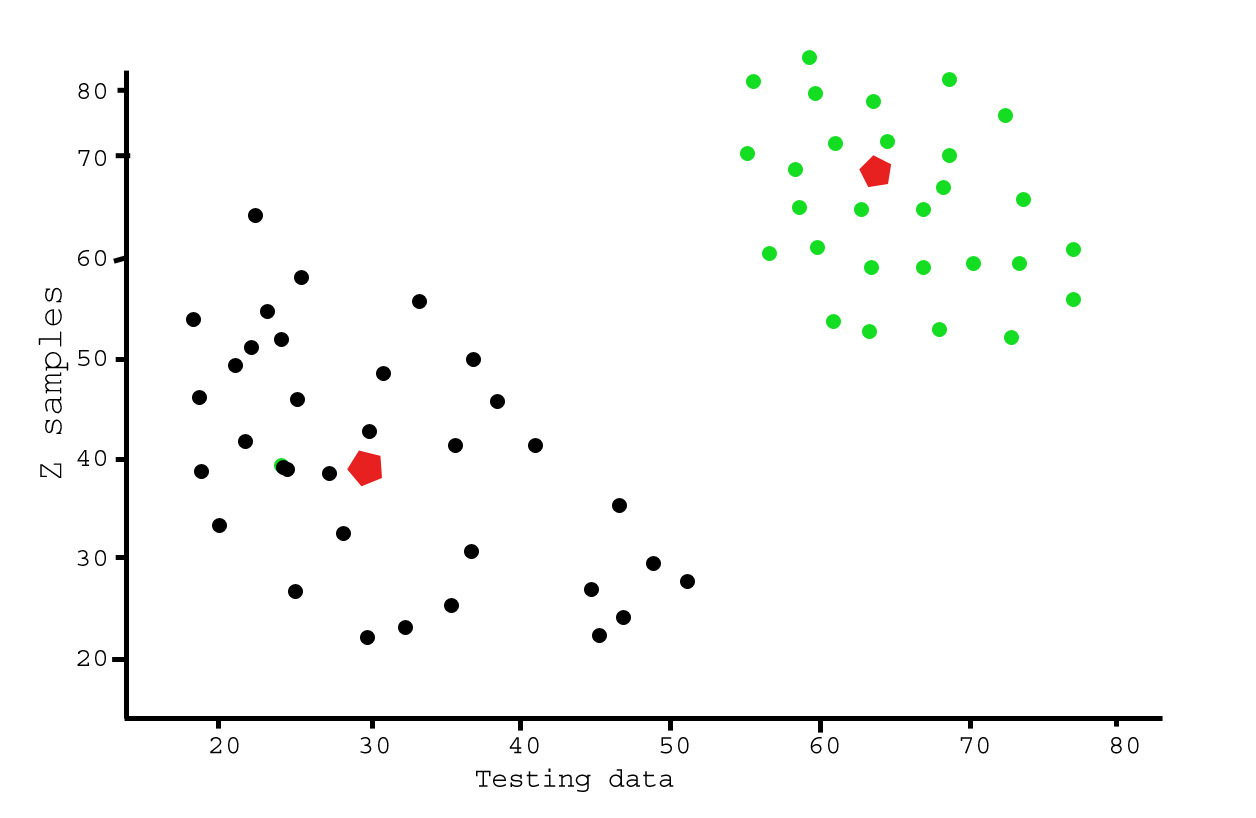
K means prediction python. K-Means is an unsupervised machine learning algorithm that groups data into k number of clusters. The worst case complexity is given by Onk2p with n n_samples p n_features. It is easy to generate.
Def predictdata centroids. The k -means algorithm does this automatically and in Scikit-Learn uses the typical estimator API. Centroids data nparraycentroids nparraydata distances for unit in data.
The first step is to randomly select k centroids where k is equal to the number of clusters you choose. Once the algorithm has been run and the groups are defined any new data can be easily assigned to the most relevant group. K-means algorithm will cluster co-offenders collaboration and dissolution of organized crime groups identifying various relevant crime patterns hidden links link prediction and statistical analysis of crime data.
K Means segregates the unlabeled data into various groups called clusters based on having similar features common patterns. From sklearncluster import affinity_propagation. The main element of the algorithm works by a two-step process called expectation-maximization.
In contrast to traditional supervised machine learning algorithms K-Means attempts to classify data without having first been trained with labeled data. Cluster_centers_ The number of iterations required to. Note that they are not in general points from X although they live in the same space.
The maximum is the number of data points that you have. And there are many more clustering algorithms available under the scikit-learn module of python some of the popular ones are. Distancesappendnpsumunit - center 2 distances npreshapedistances datashape closest_centroid npargmindist for dist in distances printclosest_centroid.
The k-means problem is solved using either Lloyds or Elkans algorithm. In general it can help you find meaningful structure among your data group similar data together and discover underlying patterns. Perform K means clustering on different values of K ranging from 1 to any upper limit.
Inertia_ Final locations of the centroid print kmeans. Optimization tools can help you with this as youll see in the last part of this tutorial. This means using all neighbors.
Where the center of each cluster is. The number of clusters is user-defined and the algorithm will try to group the data even if this number is not optimal for the specific case. K-Means Elbow Method code for Python.
The minimum value of k is 1. Create your clusters. Centroids are data points representing the center of a cluster.
Pick a value for k the number of clusters to create Initialize k centroids starting points in your data. K means Clustering - Implemented K-means clustering using pyspark - Kmeanspy contains the source code The following commands are used to run the application. Here we are taking the upper limit as 10.
Which cluster each data point belongs to. 1 Put the input files and Kmeanspy file in home folder of dsba hadoop cluster using winscp or using the following commands. This means using only one neighbor for the prediction.
Machine learning practitioners generally use K means clustering algorithms to make two types of predictions. The K-Means algorithm written from scratch using the Python programming language. K-means clustering python from sklearn.
Predicting iris flower species with k-means clustering in python Clustering is an unsupervisedlearning method that allows us to group set of objects based on similar characteristics. K means works through the following iterative process. The K-means algorithm aims to choose centroids that minimise the inertia or within-cluster sum-of-squares criterion.
From sklearncluster import k_means. The means are commonly called the cluster centroids. The value of k is something that the user defines.
Kmeans KMeans n_clusters 10max_iter 1000 Make a pipeline chaining normalizer and kmeans. K-Means Clustering is an unsupervised machine learning algorithm. Scp Chicago_Crimes_updatedcsv sbilgunddsba-hadoopuncceduuserssbilgund scp Kmeanspy.
K-means algorithm plays an important role in analyzing and predicting crimes. The average complexity is given by Ok n T where n is the number of samples and T is the number of iteration. WCSS 1- Calculate the sum of squared distance of all points to the centroid.
Fit x_train Replace your training dataset instead of x_train The lowest SSE value print kmeans. Pipelinefit movements labels pipelinepredict movements The. Conventional k -means requires only a few steps.
From sklearncluster import MiniBatchKMeans. Vassilvitskii How slow is the k-means method. Python Implementation of K means Clustering.
From sklearncluster import KMeans kmeans KMeansn_clusters4 kmeansfitX y_kmeans kmeanspredictX Lets visualize the results by plotting the data colored by these labels. Pipeline make_pipeline normalizerkmeans Fit pipeline to daily stock movements. Cluster import KMeans kmeans KMeans init random n_clusters 3 n_init 10 max_iter 300 random_state 42 kmeans.
For each K calculate WCSS.

K Means Clustering How It Works Finding The Optimum Number Of Clusters In The Data By Serafeim Loukas Towards Data Science

Build K Means From Scratch In Python By Rishit Dagli Medium

K Means Clustering With Scikit Learn By Lorraine Li Towards Data Science

Posting Komentar untuk "K Means Prediction Python"